Subscribe to our newsletter
One short email when we publish. No spam, unsubscribe anytime.
Hermes Agent gets GLM-5.3 FlashX
Hermes Agent added Z.ai's GLM-5.3 FlashX to its model menus for OpenRouter and Nous Portal on September 20, 2026, according to the merged change from Nous Research. For users, the change adds another AI model to choose as the agent's brain.
What a new brain means
In its project documentation, checked on September 21, 2026, Nous Research describes Hermes as an agent with tools, saved memories and reusable skills, including scheduled tasks such as reports. In everyday terms, Hermes organises the work around the model that reads a request and helps decide what to do next.
The Hermes model guide, checked on September 21, explains how users can choose the main model separately from models assigned to individual tasks. That makes FlashX an additional choice for an existing Hermes setup.
On September 21, OpenRouter described FlashX as the speed-focused version of GLM-5.3 Flash, with output reaching up to 200 tokens, the small units used to measure text, per second. OpenRouter gives that figure as an upper limit; this article includes no independent timing test of everyday Hermes tasks.
The cost, in plain numbers
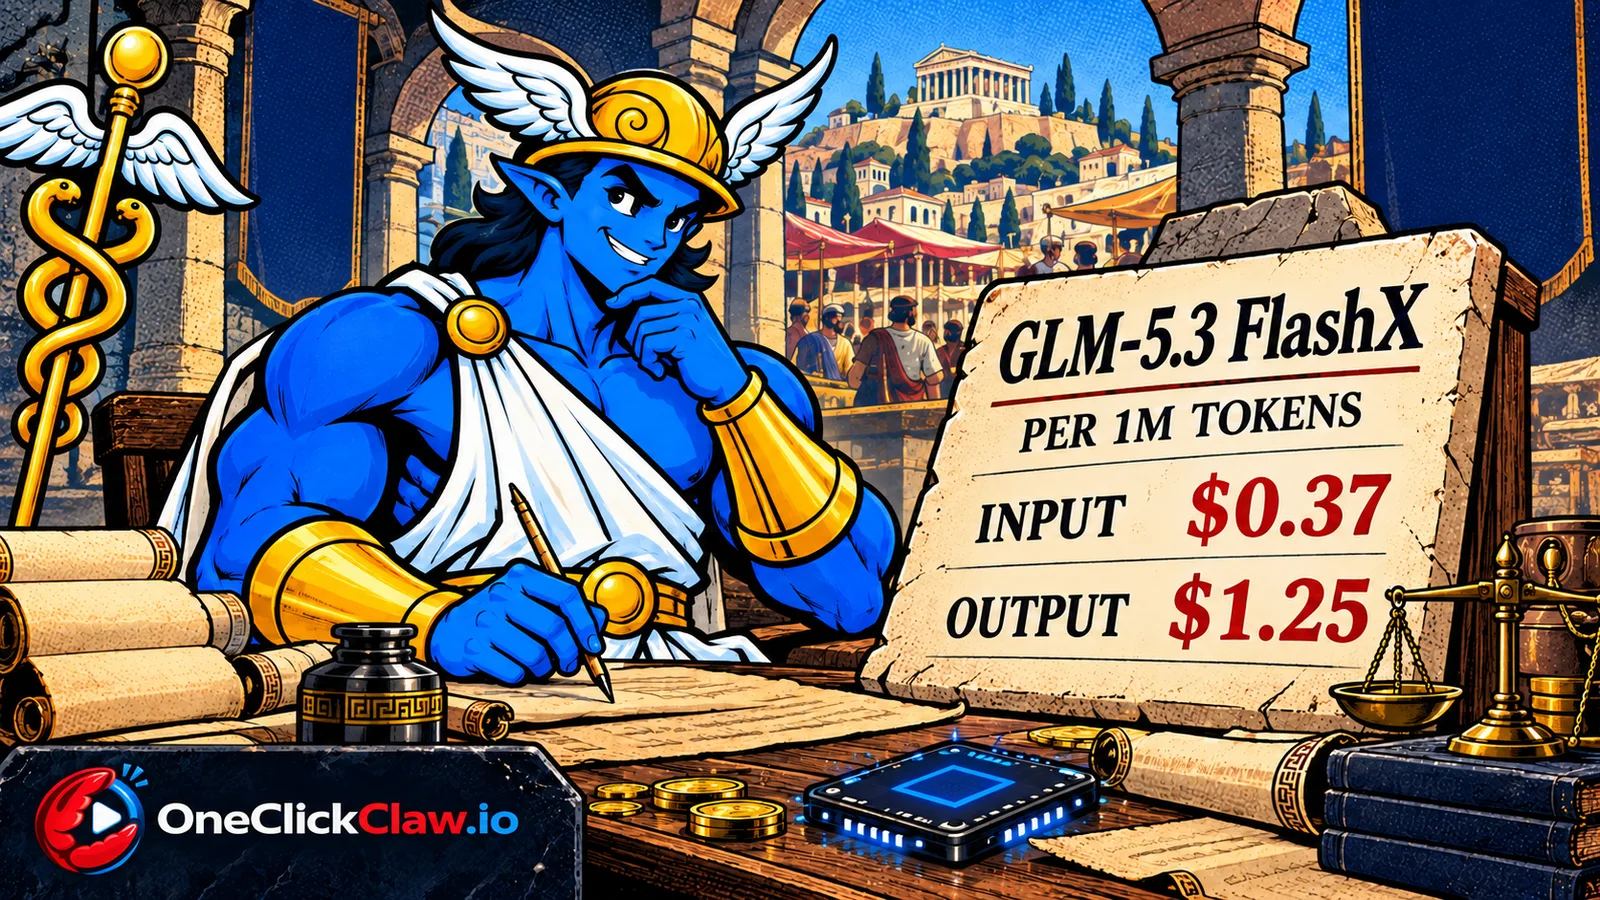
On September 21, OpenRouter listed FlashX at $0.37 per million input tokens and $1.25 per million output tokens. Tokens are the small units used to measure the material a model processes; input covers what goes in and output covers what it generates.
| What is measured | Price per million tokens |
|---|---|
| Input | $0.37 |
| Output | $1.25 |
Source: OpenRouter, September 21, 2026.
An illustrative calculation using those listed rates puts 100,000 input tokens plus 10,000 output tokens at $0.0495, about five US cents. This example assumes ordinary input pricing and counts only the specified model usage; a monthly estimate needs the total usage across all requests.
OpenRouter's usage documentation, checked on September 21, says each response includes token counts and the amount charged, with separate details for reasoning and cached material when available. For a reader comparing costs, those records provide the figures behind the bill.
How much material it can work with
The September 20 Hermes change sets FlashX's context window at 1,048,576 tokens, just over one million. The context window is the working space available for the material involved in a model request.
Hermes keeps saved memories and skills in separate locations, according to its configuration documentation, checked on September 21. A useful way to picture that distinction is a reading desk for the current task and a filing cabinet for information kept between sessions.
Where to find the choice
The September 20 merged change names the model z-ai/glm-5.3-flashx and adds it to both providers' menus in the main development branch. Availability of that menu entry on an individual installation depends on the installed software.
The official model guide, checked on September 21, describes hermes model as an interactive way to choose a provider, connect an account and select a model. It also documents /model for changing the model inside an active conversation.
The same guide says a change saved from the dashboard applies to new sessions, while an existing chat keeps its current model. Readers can therefore check both their saved choice and the model used by the conversation already open.
During the checks recorded in the September 20 Hermes change, both providers returned capacity-limit responses to test requests. This records the result at that testing time; current response availability requires a fresh request.
The server and the model have separate costs
On September 21, OneClickClaw's Hermes hosting page described a dedicated EU server with managed maintenance and model usage paid through the customer's connected provider. The hosting covers the machine that runs Hermes; the provider measures the AI usage.
OneClickClaw also lists a seven-day free trial for Hermes hosting. Confirmation that FlashX appears in every OneClickClaw installation remains pending as of September 21, 2026.
Source: github.com
Helpful documentation
Want your own Hermes agent running without the setup? We host it on a dedicated EU server. Free for 7 days, no credit card.
Start your free trialGet notified when we publish new articles
No spam, unsubscribe anytime.
By subscribing, you agree to our Privacy Policy.